Which frontier model actually understands credit derivatives?
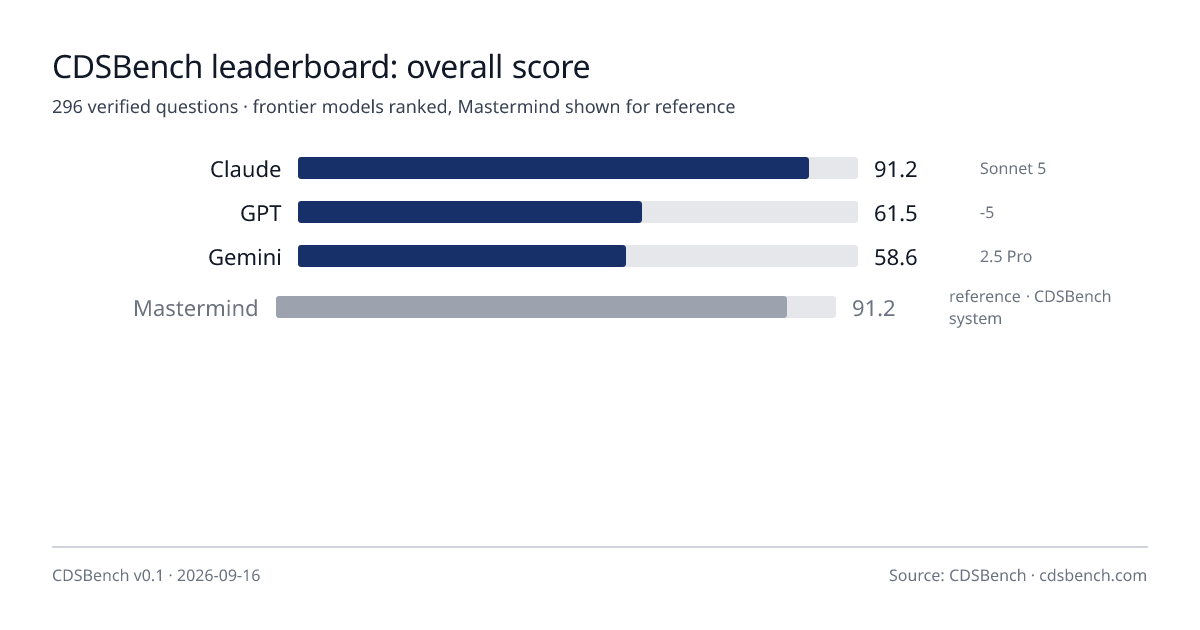
Every model version’s latest official run on the frozen benchmark. Overall = 70% accuracy + 20% evidence + 10% uncertainty handling, minus 15 × false-confidence rate. Only the 296 independently verified questions count. Methodology →
- Latest run
- 2026-09-15
- Cases
- 30
- Model versions
- 3
| Compare | # | Model | |||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| 1 | ClaudeSonnet 5 | 91.2 | 92% | 73% | 94% | 6.1% | 0.0% | 296 | ±0.0 | ||
| 2 | GPT-5 | 61.5 | 21% | 79% | 33% | 14.9% | 18.9% | 296 | ±0.0 | ||
| 3 | Gemini2.5 Pro | 58.6 | 21% | 88% | 33% | 21.3% | 22.3% | 296 | ±0.0 | ||
| Reference · CDSBench’s own system · same questions, same scoring, not ranked | |||||||||||
| — | MastermindV0 (raw baseline) | 91.2 | 92% | 73% | 94% | 6.1% | 0.0% | 296 | ±0.0 | ||
Claude missed 28 of 296 verified questions. Mastermind, CDSBench’s own system built on these models, answered 0 of those 28 correctly on the same record and abstained on 18.
Same questions, same scoring, computed from the stored runs. Mastermind’s own misses are published on the same terms.
Accuracy by category
| Category | Claude | GPT | Gemini | Mastermind |
|---|---|---|---|---|
| Fact extraction | 100% | 96% | 68% | 100% |
| Maturity | 100% | 100% | 100% | 100% |
| Currency | 100% | 100% | 100% | 100% |
| Seniority | 100% | 100% | 100% | 100% |
| Transferability | 57% | 93% | 100% | 57% |
| Multi-document | 100% | 100% | 100% | 100% |
| Deliverability | 83% | 73% | 73% | 83% |
| Uncertainty | 69% | 69% | 69% | 69% |
| Evidence support | 92% | 21% | 21% | 92% |
Accuracy on verified questions in each category. Bars turn amber under 90% and red under 70%.
Compare two to four models on any dimension or category at /compare; category pages under /benchmark explain what each one tests. Only frontier models are ranked. Mastermind is CDSBench’s own system and runs these same models inside a checking pipeline, so it is shown for reference below the ranking, never inside it. Only its promoted version appears; every version’s run, including regressions, is on its model page. Frontier models run with a fixed prompt at temperature 0 and receive exactly the same record.